approach
ExArch
ExArch – LLM-based Architecture Component Name Extraction for TLR between Software Architecture Documentation and Code.
- SAD linked with Code
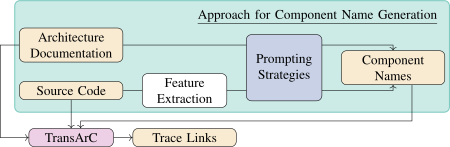
ExArch extends the TransArC idea by using an LLM to generate a simple SAM. In this approach, instead of requiring a hand-made SAM, a large language model (GPT-4o) is prompted to extract the main component names from the SAD and the source code. These names serve as a minimal architecture model, i.e. a simple SAM that is just a list of components. Then, as in TransArC, these LLM-derived components are matched to code. The goal is to bridge the SAD–code gap without manual modeling.
- How it works: The code goes through a feature extraction step, and both the software architecture text and the extracted code features feed the prompting strategies, which ask the LLM to list likely component names. That list of names forms the simple SAM. Finally, code elements with matching names or descriptions are linked to the documentation. This pipeline avoids needing an explicit UML model.
- Effectiveness: ExArch achieved very competitive results. Using GPT-4o, it obtained a weighted F1 of about 0.86, nearly as good as the original TransArC with a hand-made model (F1 0.87). It also substantially outperformed the ArDoCode baseline (which scored ~0.62). This shows that LLMs can automatically infer the key architectural components.
- Extension: The TAAS journal extension, “Who’s Who? LLM-assisted Software Traceability with Architecture Entity Recognition”, adds ArTEMiS.